No—not reliably enough to prove who wrote a passage. AI detectors can provide a useful signal for deciding what to review, but their scores change with the detector and model version, text length, language, genre, and the amount of editing. Human writing can be flagged, while AI-written text can be missed or altered to evade detection.
The defensible use is contextual: treat a score as one piece of information alongside drafts, version history, sources, the assignment or publication policy, and the writer’s explanation. A detector result by itself is not a sound finding of misconduct or proof of authorship.
What an AI detector can—and cannot—establish
Most detectors estimate whether linguistic patterns resemble text in a model’s training or calibration data. They do not observe the writer, the computer used, or the exact process that produced the words. The output is therefore a classification or probability-like score, not a chain of custody.
- A positive result means the submitted text resembles material the tool associates with AI generation. It does not identify a particular model, person, date, or prompt.
- A negative result means the tool did not find enough of those patterns. It does not prove that a human wrote the passage.
- A percentage is meaningful only with the tool’s definition, threshold, language model, minimum length, and error rates. Percentages from different products are not interchangeable.
OpenAI’s educator guidance warns that detectors can mislabel human writing and that small edits can evade detection. It also says ChatGPT cannot reliably determine whether a passage was written by AI. Asking a chatbot to identify its own authorship is not evidence; OpenAI describes those answers as random and without a factual basis. See OpenAI’s guidance for educators.
Recommended Free Tools
#1 Best Overall

- HD streaming made simple: With America’s number 1 TV streaming platform,* exploring popular apps—plus tons of free movies, shows, and live TV—is as easy as it is fun. *Based on hours streamed—Hypothesis Group
- Compact without compromises: The sleek design of Roku Streaming Stick won’t block neighboring HDMI ports, and it even powers from your TV alone, plugging into the back and staying out of sight. No wall outlet, no extra cords, no clutter.
- No more juggling remotes: Power up your TV, adjust the volume, and control your Roku device with one remote. Use your voice to quickly search, play entertainment, and more.
- Shows on the go: Take your TV to-go when traveling—without needing to log into someone else’s device.
- TV, simplified: With setup that only takes minutes, a simple-to-navigate Home Screen, and an uncluttered remote control that does all you need—Roku makes it easier to watch the TV you love.
OpenAI’s archived classifier announcement states, “Our classifier is not fully reliable,” and says it should not be used as a primary decision-making tool, but as a complement to other ways of determining a text’s source. Those statements describe that classifier and its limitations, not a guarantee about every current product.
Why detector reliability changes from one case to another
Text length and the amount of qualifying prose
Very short passages contain too little statistical information. OpenAI reported that its classifier was very unreliable below 1,000 characters. A title, a paragraph, a caption, a quotation, or a short answer can therefore produce an unstable result. Code and lists are also unlike the prose on which many systems are trained.
Commercial reports commonly exclude material that does not meet their length or formatting rules. A result from a 2,000-word essay cannot be assumed to apply to a 120-word email or a documentary subtitle track.
Rank #2

- Ultra-speedy streaming: Roku Ultra is 30% faster than any other Roku player, delivering a lightning-fast interface and apps that launch in a snap.
- Cinematic streaming: This TV streaming device brings the movie theater to your living room with spectacular 4K, HDR10+, and Dolby Vision picture alongside immersive Dolby Atmos audio.
- The ultimate Roku remote: The rechargeable Roku Voice Remote Pro offers backlit buttons, hands-free voice controls, and a lost remote finder.
- No more fumbling in the dark: See what you’re pressing with backlit buttons.
- Say goodbye to batteries: Keep your remote powered for months on a single charge.
Language and writing background
Models calibrated on English may react to features of translation, second-language writing, or a constrained vocabulary rather than to AI authorship. OpenAI described weaker performance in languages other than English. A study by Liang and colleagues found an average false-positive rate of 61.22% across seven detectors on 91 TOEFL essays written by non-native English users. Eighteen essays were flagged by all seven systems and 89 by at least one. Those figures describe that study’s detectors, essays, and period; they are not a universal rate for every language or current service. The study is available at arXiv:2304.02819.
Genre, formulaic language, and constrained style
Academic introductions, legal clauses, laboratory methods, accessibility captions, scripts, and heavily edited corporate copy often use predictable structures. Predictability can look machine-generated even when a person followed a template or an editor’s style sheet. Conversely, a model prompted to imitate a distinctive voice, or a human text substantially rewritten by software, may look less predictable to a detector.
Editing, paraphrasing, and distribution shift
Changing wording, sentence order, punctuation, or paragraph breaks can alter a score. OpenAI reported that its classifier was vulnerable to edits and to distribution shifts—cases where the submitted text differs from the material used to develop the classifier. A detector trained on one generation of models may also behave differently after a model update, a new writing assistant, or a change in the threshold used to display results.
Rank #3

- 4K streaming made simple:With America’s number 1 TV streaming platform,* exploring popular apps—plus tons of free movies, shows, and live TV—is as easy as it is fun. *Based on hours streamed—Hypothesis Group
- 4K picture quality: With Roku Streaming Stick Plus, watch your favorites with brilliant 4K picture and vivid HDR color.
- Compact without compromises: Our sleek design won’t block neighboring HDMI ports, and it even powers from your TV alone, plugging into the back and staying out of sight. No wall outlet, no extra cords, no clutter.
- No more juggling remotes: Power up your TV, adjust the volume, and control your Roku device with one remote. Use your voice to quickly search, play entertainment, and more.
- Shows on the go: Take your TV to-go when traveling—without needing to log into someone else’s device.
What published performance numbers actually show
Performance claims are test-specific. A useful report identifies the population, language, model or detector version, threshold, and both kinds of error: false positives (human text flagged) and false negatives (AI text missed).
| System or study | Material tested | Reported result | How to interpret it |
|---|---|---|---|
| OpenAI classifier (2023, later retired) | English challenge set | 26% of AI-written samples were identified as likely AI-written; 9% of human-written samples were mislabeled | A historical result for one classifier and test set, not a benchmark for all detectors. OpenAI discontinued the classifier on July 20, 2023, citing low accuracy. Announcement |
| Liang et al. (2023) | 91 TOEFL essays by non-native English writers; seven detectors | 61.22% average false-positive rate; 18 essays flagged by all seven and 89 by at least one | Shows how severe false positives can be for this population and detector set. It cannot be generalized to every current product or writer. |
| Dik et al. (2025 preprint) | 28 AI-written and 50 human-written papers; GPTZero tested across essay lengths | Strong identification for the sampled AI papers, but fluctuating outputs and some false positives on human papers; exact rates not stated | A small preprint sample. It supports caution, not a population-wide accuracy claim. Study |
A detector can have high sensitivity on a curated set and still be unsuitable for disciplinary decisions if its false-positive rate is unacceptable in the real population. “Accuracy” without the test population and error definitions hides that trade-off.
Free tools Windows power users keep installed
One-click scans. No signup required.
How to read a Turnitin AI Writing Report
Turnitin’s current documentation defines its displayed percentage as the share of qualifying prose that its AI-writing model identifies as likely AI-generated or likely generated and then modified by an AI paraphrasing tool. The report itself says false positives are possible. Its requirements and labels can change, so consult the current report guide when interpreting a live case.
Rank #4
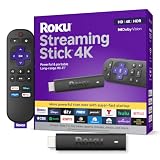
- Stunning 4K and Dolby Vision streaming made simple: With America’s number 1 TV streaming platform,* exploring popular apps—plus tons of free movies, shows, and live TV—is as easy as it is fun. *Based on hours streamed—Hypothesis Group
- Breathtaking picture quality: Stunningly sharp 4K picture brings out rich detail in your entertainment with four times the resolution of HD. Watch as colors pop off your screen and enjoy lifelike clarity with Dolby Vision and HDR10+.
- Seamless streaming for any room: With Roku Streaming Stick 4K, watch your favorite entertainment on any TV in the house, even in rooms farther from your router thanks to the long-range Wi-Fi receiver.
- Shows on the go: Take your TV to-go when traveling—without needing to log into someone else’s device.
- Compact without compromises: Our sleek design won’t block neighboring HDMI ports, so you can switch from streaming to gaming with ease. Plus, it’s designed to stay hidden behind your TV, keeping wires neatly out of sight
- The report requires at least 300 words of qualifying prose and supports up to 30,000 words.
- The guide lists English, Spanish, Japanese, and Arabic as supported languages.
- Current reports suppress exact scores below 20% and show an asterisk instead, because low percentages have a higher incidence of false positives.
- The English detector includes AI-paraphrasing and bypasser detection; the Spanish and Japanese models have different capabilities. A score from one language model or product version should not be treated as equivalent to another.
For an editor or instructor, the percentage is a prompt to inspect the highlighted passages and the surrounding evidence. It is not the percentage probability that a named person used AI, nor the percentage of the entire submission if non-qualifying material was excluded.
Provenance signals are a different kind of check
Provenance systems look for a supported signal associated with a particular generation service. OpenAI’s provenance guidance describes tools designed to find signals associated with OpenAI content, not to detect material made by every AI system.
A detected signal does not identify the author or explain why the content was produced. Short passages and code are difficult cases, detection rates vary by language, and the documented access is limited to qualifying academic and research organizations; academic-integrity checking of student work is outside the stated access scope. A provenance hit and a general detector score therefore answer different questions: one asks whether a supported signal is present, while the other estimates whether the text resembles a detector’s AI examples.
Best Value

- The Google TV Streamer (4K) delivers your favorite entertainment quickly, easily, and personalized to you[1,2]
- HDMI 2.1 cable required (sold separately)
- See movies and TV shows from all your services right from your home screen[2]; and find new things to watch with tailored recommendations for everyone in your home based on their interests and viewing habits
- Watch live TV and access over 800 free channels from Pluto TV, Tubi, and more[3]; if you find an interesting show or movie on your TV, mobile app, or Google search, you can easily add it to your watchlist, so it’s ready when you are[2]
- Up to 4K HDR with Dolby Vision delivers captivating, true-to-life detail[4]; and you can connect speakers that support Dolby Atmos for more immersive 3D sound
A responsible workflow for educators and editors
- Start with the governing policy. Define what assistance is allowed, what must be disclosed, and what evidence is required. Do not invent a violation from a score when the policy does not define one.
- Preserve the submitted material. Keep the original file, timestamps, tracked changes, version history, bibliography, and any relevant recording or production notes. A later re-save can change metadata.
- Check eligibility before running a tool. Confirm the minimum word count, supported language, prose requirement, and model/version date. Record the exact product and settings so a result can be reproduced as far as the service allows.
- Read the passage, not just the number. Examine the highlighted sentences, factual accuracy, citations, and whether the style matches the assignment or the writer’s earlier work. Formulaic language and translation effects deserve special caution.
- Ask for process evidence. Request drafts, outlines, source notes, edit history, or a short explanation of decisions in the work. OpenAI’s educator guidance suggests asking students to share specific ChatGPT conversations where relevant and to log and cite sources when AI was used.
- Invite a response. Give the writer the passages and the policy basis, and allow an explanation or correction. Do not ask ChatGPT whether it wrote the text and treat the reply as proof.
- Corroborate before deciding. Consider source fabrication, unexplained changes in voice, missing drafts, or a direct admission together with the detector output. A high score alone should not determine a grade, rejection, or disciplinary finding.
- Document uncertainty and proportionality. Record the detector’s limitations, the evidence reviewed, and why the final action fits the policy. If the evidence remains ambiguous, use a formative response—such as a rewrite, oral explanation, or citation check—rather than presenting an inference as a fact.
How to compare detector tools without being misled
When evaluating a service for a newsroom, school, or production team, ask for evidence on each of these axes:
| Question | Why it matters |
|---|---|
| Which languages and text types were tested? | Results on English essays do not establish performance on scripts, captions, code, translations, or multilingual work. |
| What minimum length and formatting are required? | Short or mixed-format submissions may be excluded or produce unstable scores. |
| Which model and version date produced the result? | Updates and threshold changes can make scores incomparable over time. |
| Are false positives and false negatives reported separately? | A single “accuracy” figure can conceal harmful errors in either direction. |
| Were edited, paraphrased, or translated passages tested? | Real submissions often contain revision, copy editing, or language transfer that changes detector behavior. |
| Is the output evidence or a review prompt? | A tool that clearly labels uncertainty is safer than one that implies authorship from a percentage. |
Ask vendors to provide the tested population, prevalence of AI text, decision threshold, confidence intervals where available, and examples of failure cases. Without that information, a headline claim such as “high accuracy” cannot be applied responsibly to your writers or students.
Common situations and the safest interpretation
- A high score on a long English essay: review the highlighted text and process evidence. The score raises a question; it does not identify the author.
- A low score or no score: do not treat it as clearance. The detector may have missed AI text, or the passage may not have met its requirements.
- Conflicting tools: differences are expected because models, thresholds, and training sets differ. Resolve the conflict with provenance and process evidence, not by choosing the more alarming number.
- A short answer, code sample, caption, or transcript: treat the output as especially weak unless the tool documents validation for that format.
- A non-native English writer or highly formulaic assignment: apply heightened scrutiny to false-positive risk and provide a way to explain drafting and language choices.
- Text edited after generation: assume the score may move in either direction. Editing can reduce detectable patterns, while polishing human prose can make it more regular.
Bottom line for documentary and editorial work
AI detectors are screening instruments, not authorship tests. Their published results include substantial misses and false alarms, and their behavior depends on language, length, genre, editing, and version. Use them, if policy permits, to decide where a human should look more closely. Make the final judgment from the complete record—drafts, sources, version history, disclosures, and the writer’s explanation—rather than from a percentage presented without context.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →

Say something about this film