The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →AI systems are tested by defining the job they are meant to do, measuring their performance on data that reflects expected use, checking outcomes across relevant groups, probing failure modes, and monitoring them after deployment. A benchmark score describes how a system performed on a particular test under particular conditions; it does not establish that the system is accurate, fair, or reliable for every purpose.
Testing starts with the system’s intended use
There is no meaningful accuracy test without a defined task and setting. An evaluator first needs to know what the system is supposed to do, who will use it, who may be affected by its output, and what happens when it is wrong. The same model can perform acceptably for one task and poorly or harmfully for another.
For example, a system that sorts documents for later human review has different consequences from one that makes or strongly influences a consequential decision. The evaluation should reflect the actual role of the system, the people and processes around it, the operating environment, and the severity of plausible errors. NIST’s AI Risk Management Framework (AI RMF 1.0) says measurement choices depend on the context in which an AI component operates.
This framing also determines what counts as evidence. A test set built from common, clean examples may say little about performance on unusual inputs, different populations, or a changed operating environment. Before scoring a model, evaluators therefore identify likely conditions of use and the failure modes that matter there.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
#1 Best Overall

- HD streaming made simple: With America’s number 1 TV streaming platform,* exploring popular apps—plus tons of free movies, shows, and live TV—is as easy as it is fun. *Based on hours streamed—Hypothesis Group
- Compact without compromises: The sleek design of Roku Streaming Stick won’t block neighboring HDMI ports, and it even powers from your TV alone, plugging into the back and staying out of sight. No wall outlet, no extra cords, no clutter.
- No more juggling remotes: Power up your TV, adjust the volume, and control your Roku device with one remote. Use your voice to quickly search, play entertainment, and more.
- Shows on the go: Take your TV to-go when traveling—without needing to log into someone else’s device.
- TV, simplified: With setup that only takes minutes, a simple-to-navigate Home Screen, and an uncluttered remote control that does all you need—Roku makes it easier to watch the TV you love.
How accuracy is measured
Accuracy usually means how often a system’s outputs match an accepted reference or outcome on a defined test. That simple description hides important choices: how the reference was established, which examples were included, what counts as a correct answer, and whether all errors have similar consequences.
For a classification task, evaluators often examine several measures rather than relying on one overall score:
- Accuracy: the share of tested cases classified correctly. It can be misleading when one outcome is much more common than another.
- Precision: among cases the system labels as positive, the share that are actually positive. It helps characterize false alarms.
- Recall: among cases that are actually positive, the share the system identifies. It helps characterize missed cases.
- False-positive and false-negative rates: the frequency of each type of error, considered separately. Which matters more depends on the application and the consequences of the mistake.
These measures can move in different directions. A threshold change might catch more true cases while also creating more false alarms. The appropriate balance is a decision about the task’s error costs, not a universal property of the model. NIST’s AI measurement and evaluation guidance emphasizes realistic, clearly defined test sets and disclosure of test methods, alongside consideration of different error rates and data segments where relevant.
The test data should be held out from model development and chosen to resemble expected use. Evaluators should document how examples were selected and labeled, the evaluation method, and the conditions under which results were obtained. NIST’s AI RMF 1.0 states: “Accuracy measurements should always be paired with clearly defined and realistic test sets – that are representative of conditions of expected use – and details about test methodology; these should be included in associated documentation.”
Free tools Windows power users keep installed
One-click scans. No signup required.
Rank #2

- Ultra-speedy streaming: Roku Ultra is 30% faster than any other Roku player, delivering a lightning-fast interface and apps that launch in a snap.
- Cinematic streaming: This TV streaming device brings the movie theater to your living room with spectacular 4K, HDR10+, and Dolby Vision picture alongside immersive Dolby Atmos audio.
- The ultimate Roku remote: The rechargeable Roku Voice Remote Pro offers backlit buttons, hands-free voice controls, and a lost remote finder.
- No more fumbling in the dark: See what you’re pressing with backlit buttons.
- Say goodbye to batteries: Keep your remote powered for months on a single charge.
A high score on that set is evidence about performance on those examples under those conditions. It is not proof that the same result will hold for different users, settings, or future data. The test’s representativeness and limits are part of the result, not footnotes to ignore.
How evaluators look for bias
Bias can enter through more than one part of an AI system. NIST distinguishes systemic sources, computational and statistical sources, and human-cognitive sources. In practice, problems may relate to the data, the way outcomes or categories are defined, the model and its design, or decisions made by people who build, deploy, or interpret it. NIST’s report Mitigating AI/ML Bias in Context stresses that bias must be assessed in the context of the application.
A common evaluation step is to disaggregate results: calculate relevant performance and error measures for meaningful groups or conditions instead of reporting only an aggregate. A system can appear strong overall while performing unevenly for a subgroup. Which groups to examine depends on the people affected, the use case, available and appropriate data, and the likely sources of harm.
Group comparisons do not automatically settle whether a system is fair. The choice of group categories, labels, thresholds, and acceptable tradeoffs involves context and stakeholder judgment. Different fairness measures can conflict, and a numerical difference needs interpretation in light of the system’s purpose and the real-world process it affects. NIST cautions that trustworthiness characteristics may involve tradeoffs; they cannot be collapsed into one universal fairness score.
Recommended Free Tools
Rank #3

- 4K streaming made simple:With America’s number 1 TV streaming platform,* exploring popular apps—plus tons of free movies, shows, and live TV—is as easy as it is fun. *Based on hours streamed—Hypothesis Group
- 4K picture quality: With Roku Streaming Stick Plus, watch your favorites with brilliant 4K picture and vivid HDR color.
- Compact without compromises: Our sleek design won’t block neighboring HDMI ports, and it even powers from your TV alone, plugging into the back and staying out of sight. No wall outlet, no extra cords, no clutter.
- No more juggling remotes: Power up your TV, adjust the volume, and control your Roku device with one remote. Use your voice to quickly search, play entertainment, and more.
- Shows on the go: Take your TV to-go when traveling—without needing to log into someone else’s device.
Evaluators should also consider whether apparent disparities reflect the system, the data, the surrounding workflow, or multiple factors together. For example, a label used as the “correct” answer may itself be an imperfect proxy for the outcome that matters. Measuring the model against that label can reproduce limitations in the label rather than resolve them. The test report should therefore explain what was measured and why the chosen comparisons are relevant.
What reliability testing adds
Reliability concerns whether a system continues to behave dependably across conditions and over time, not just whether it performs well on a single evaluation. A model can be accurate on familiar examples yet fail when inputs change, when it encounters edge cases, or when the environment differs from the one represented in development data.
Evaluators probe robustness by varying inputs and testing conditions beyond the most routine cases. They look at how performance changes when data differs from expected patterns, how severe failures are, and whether the system can be safely interrupted, corrected, or recovered. Reliability is therefore not only a score: failure severity and the available response to a failure matter too.
Deployment can change the conditions a system encounters. Usage patterns, data, and operational processes may shift, so a pre-deployment result cannot serve as a permanent guarantee. NIST’s AI RMF Playbook’s Measure guidance and its description of AI risks and trustworthiness support ongoing measurement and attention to changes that may affect system performance.
Rank #4
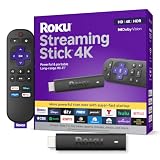
- Stunning 4K and Dolby Vision streaming made simple: With America’s number 1 TV streaming platform,* exploring popular apps—plus tons of free movies, shows, and live TV—is as easy as it is fun. *Based on hours streamed—Hypothesis Group
- Breathtaking picture quality: Stunningly sharp 4K picture brings out rich detail in your entertainment with four times the resolution of HD. Watch as colors pop off your screen and enjoy lifelike clarity with Dolby Vision and HDR10+.
- Seamless streaming for any room: With Roku Streaming Stick 4K, watch your favorite entertainment on any TV in the house, even in rooms farther from your router thanks to the long-range Wi-Fi receiver.
- Shows on the go: Take your TV to-go when traveling—without needing to log into someone else’s device.
- Compact without compromises: Our sleek design won’t block neighboring HDMI ports, so you can switch from streaming to gaming with ease. Plus, it’s designed to stay hidden behind your TV, keeping wires neatly out of sight
Monitoring should connect observed changes to an action: investigate, adjust, restrict, or pause use when appropriate. The evaluation plan should identify who reviews signals, what conditions trigger intervention, and how the system will be reassessed if its data or use changes. Monitoring is not a substitute for a good initial test; it addresses risks that cannot be fully anticipated before deployment.
Why evaluators use several kinds of tests
Different evaluation modes reveal different weaknesses. A model test can measure defined tasks under controlled conditions; red-teaming deliberately probes for failure modes; blind-data testing can reduce the chance that public test material was encountered during training; and field testing can reveal behavior in a real or realistic operating environment. No single mode covers every risk or reproduces every deployment setting.
Public benchmarks are useful for repeatable comparisons, but a score can be less informative if test material was included in training or otherwise familiar to the system. NIST’s AI Technology Evaluation (AITE) describes evaluation using blind data in a sequestered environment as a way to mitigate benchmark contamination. That safeguard does not by itself make the test representative of real use.
NIST’s ARIA initiative and AITE overview illustrate the role of evaluation settings and methods beyond a single public score. NIST says its measurement work has “designed and conducted hundreds of evaluations of thousands of AI systems.” That is a description of the organization’s historical evaluation activity, not a statistic about the accuracy or quality of AI systems generally.
Best Value

- The Google TV Streamer (4K) delivers your favorite entertainment quickly, easily, and personalized to you[1,2]
- HDMI 2.1 cable required (sold separately)
- See movies and TV shows from all your services right from your home screen[2]; and find new things to watch with tailored recommendations for everyone in your home based on their interests and viewing habits
- Watch live TV and access over 800 free channels from Pluto TV, Tubi, and more[3]; if you find an interesting show or movie on your TV, mobile app, or Google search, you can easily add it to your watchlist, so it’s ready when you are[2]
- Up to 4K HDR with Dolby Vision delivers captivating, true-to-life detail[4]; and you can connect speakers that support Dolby Atmos for more immersive 3D sound
A practical evaluation sequence
- Define the use. Describe the task, intended users, affected groups, operating environment, and the decisions or actions influenced by the output. List plausible harmful failure modes and their severity.
- Choose measures that match the risk. Select task metrics such as accuracy, precision, recall, and false-positive or false-negative rates according to the cost of each type of error. Explain why those measures are appropriate rather than defaulting to a convenient overall score.
- Build a representative held-out test. Use data that resembles expected use, and check whether it covers meaningful populations, conditions, and edge cases. Record how the data was selected, labeled, and kept separate from development.
- Break results down where it matters. Examine relevant groups, contexts, and error types. State how categories and comparisons were selected, and interpret differences in the application’s social and operational context.
- Probe beyond routine examples. Vary or stress inputs, red-team plausible failures, and consider blind-data or field evaluation where a standard benchmark cannot answer the important questions.
- Plan for operation after launch. Monitor relevant performance and changes in data or use. Assign responsibility for review, define intervention paths, and revisit metrics when operating conditions shift.
- Publish the scope and limits. Report what was measured and what was not, the system version and test conditions, the method and data, observed limitations, and where results may not generalize.
How to compare two AI systems fairly
A useful comparison holds the task and data conditions constant. Otherwise, a difference in scores may reflect different tests rather than a difference between systems. A comparison should include the dimensions that matter for the intended use:
- Performance on the same task and test data, including relevant error types.
- Outcomes for relevant groups or operating contexts, not just aggregate results.
- Robustness when inputs or data distributions change.
- Repeatability across time or evaluation runs, where assessed.
- Severity of failures and the ability to recover or intervene.
- How closely the evaluation resembles the conditions in which each system will be used.
Report tradeoffs rather than combining them into a single “trustworthy” ranking. One system may have fewer missed cases but more false alarms; another may perform more consistently across a tested set of contexts but be weaker on the primary task. Which difference matters most depends on the use and its consequences. NIST’s framework treats trustworthiness as contextual and recognizes that characteristics can conflict.
What an evaluation report should and should not claim
A useful report lets readers understand what the score means and where it stops applying. At minimum, it should identify the intended use, system version, test data and selection method, metrics, evaluation conditions, relevant subgroup results, limitations, and the scope of conclusions. If conditions change, the report or later assessment should make clear whether old results still apply.
Claims should match the evidence. “The system achieved a given score on this test set under these conditions” is narrower and more informative than saying it is accurate in general. A test result does not establish reliable behavior in a different environment, and the absence of a measured disparity does not prove fairness in every affected context.
The NIST AI RMF is voluntary guidance; following it does not certify a system. NIST’s materials provide a framework for organizing risk measurement and evaluation, not a blanket approval of any particular model. No general-purpose statistic establishes how accurate, biased, or reliable AI systems are as a whole: those qualities depend on the system, task, test, and setting being evaluated.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.